In "Hybrid AI in the Enterprise: Cloud vs. Local Is the Wrong Debate", we described the cloud, private, edge and endpoint continuum and the governance it requires. Teams building web and mobile applications now face a more practical question: for this use case, where should the processing run, and why?
We answer it in two steps. Start from the business use case, which sets the data, volume, latency, expected quality, offline needs and budget. Then move down to the application's features, which inherit those constraints and can each run in a different place. Token economics and security are handled from this design stage onwards.
1. Start from the use cases
The business need determines the architecture. For any given use case, three locations are possible: the user's device, the organisation's infrastructure and the cloud. The matrix below gives starting points for six common use cases. They remain hypotheses, to be checked on representative data and on the devices actually in use before you commit.
| Use case | Data | Volume, latency, quality | Candidate environment | Economic rationale | Constraints |
|---|---|---|---|---|---|
| High-volume ticket classification | Internal tickets, sometimes personal data | High volume, short latency, quality measurable against history | Compact model on private infrastructure, or a specialised classifier | Low marginal cost if the volume genuinely keeps the hardware busy | Compare first with a rule or a conventional classifier; measure quality per category |
| Confidential document extraction | Contracts, HR, finance | Medium volume, accuracy first | Device or private infrastructure | Avoids transfers and long, billed contexts | Control logs, access, backups and caches; check accuracy and document provenance |
| Offline field assistant | Procedures, job data | No or unstable network, immediate response expected | Embedded model on the device | No per-call cost, but model distribution and device compatibility must be funded | Offline only if model, data and tools are on the device; a remote private server still depends on the network |
| Internal document search (RAG) | Document base with mixed access rights | Variable volume, relevance and traceability expected | RAG with a suitable model, private or cloud depending on classification | Cost driven by the size of the injected context | Filter by access rights before sending to the model; send only the useful passages |
| Complex analysis on transferable data | Data cleared for transfer | Low volume, high reasoning demands | Approved cloud model | Pay per use rather than size hardware that is rarely used | Minimise the context sent; check the provider's contractual terms |
| Stable business rule | Structured data | Deterministic result expected | Code or rules engine | No inference, near-zero cost per run | A model would add cost and variability with no benefit |
For a stable business rule, code is enough: not every task needs an LLM, or even an AI model. For the other cases, a compact model is not necessarily good enough and a large model not necessarily required. Measurements on an evaluation set settle the choice.
2. From use cases to features
In the application, a use case becomes several features, and they do not all share the same constraints. In a field assistant, for example, input help might run on the phone, procedure search on an internal server and the analysis of a complex incident on a cloud model, if the data involved can be transferred. The three locations offer different guarantees:
- An embedded model runs in the browser or on the device. Runtimes such as ONNX Runtime Web (WebAssembly, WebGPU, WebNN) , ONNX Runtime Mobile (Android, iOS) or Windows ML on Windows PCs make this possible, provided the model fits the device's memory and storage and its operators are supported by the chosen engine.
- A model hosted on private infrastructure runs on servers controlled by the organisation or its hosting provider. Data stays within that perimeter, but the application must be able to reach it over the network.
- A cloud API provides access to managed, often more capable models, billed on usage under each provider's own terms.
An internal server does not give a mobile app offline capability: a field technician with no signal can no more reach the company data centre than a cloud service. On-device inference only guarantees offline operation if the data, tools and other dependencies required are also on the device.
One decision sheet per feature
To make these choices explicit and reviewable, we recommend recording for each feature the use case it belongs to, along with:
- users and their access rights;
- the sensitivity of the data processed;
- frequency and concurrency of use;
- expected response time;
- minimum acceptable quality;
- whether offline operation is needed;
- the allocated budget;
- approved processing destinations;
- expected behaviour on failure.
3. Token economics: think in full cost
Tokens measure how much a language model consumes, but they are not enough to cost a service. Our main indicator is the cost per successful, validated task, at comparable quality. A cheap answer that has to be redone twice costs more than a correct one the first time.
What actually consumes
For a usage-billed API, the bill depends on input tokens (instructions, question, conversation history, injected document passages, tool definitions) and the output tokens generated. Less visible costs often add up on top: successive tool calls, retries after an inadequate answer, agent loops that chain several calls for a single request. Depending on the service, reasoning, caching or audio and image modalities are billed under the provider's own terms. This article assumes no pricing: price lists change quickly and should be checked when you build the estimate.
The levers
- Process frequent, well-bounded tasks locally, with compact specialised models where evaluations justify it.
- Reduce the context: send only the relevant passages, the useful history and the minimum data. Effective retrieval, filtered by access rights, cuts both cost and risk.
- Bound execution: output token caps, iteration limits for agents, maximum timeouts.
- Use a partitioned, up-to-date cache, never shared between users or customers with different access rights.
- Set quotas per user, per team and per feature.
- Escalate selectively to a more capable model, based on validated criteria.
Microsoft describes the same family of levers (caching, batching, routing, model selection) in its AI cost optimisation guide. The guide also recommends running every change through an evaluation set before deployment, to check that lower cost does not come with lower quality.
Beware of false savings: a summary produced locally before sending to the cloud reduces the volume transmitted, but it guarantees neither anonymisation nor the absence of information loss.
A hypothetical example
Take an application that receives 100,000 requests a month. Once routing is in place, 60,000 are resolved locally, 10,000 by a valid cache and 30,000 are sent to the cloud.
100,000
requests per month (hypothesis)
30,000
requests still sent to the cloud
−70%
cloud calls; savings still to be measured
Compared with a baseline where every request triggers a cloud call, cloud calls fall by 70%. That does not mean a 70% saving. The requests still sent to the cloud are often the longest and most complex, and may consume more tokens per call. Local processing has its own cost. And when a request handled locally first is then escalated, it generates a double call that must be counted in real-world measurements.
The full cost
Hybrid cost = allocated local cost + operations + cloud consumption + associated services
Allocated local cost covers depreciated or leased hardware (GPU, CPU, NPU), energy and hosting. Operations cover administration, maintenance, updates, distributing models to servers or devices, and monitoring. Associated services include retrieval and storage in particular. Each item should be counted only once: shared monitoring, for instance, should not appear under both operations and services.
Cloud cost = (billed input tokens ÷ 1 million × input price) + (billed output tokens ÷ 1 million × output price) + other applicable charges
Caching, reasoning tokens and multimedia modalities follow each provider's own price list.
Indicators to track
Beyond cost per validated task, track the local resolution rate, tokens per task, escalation rate, retries, 95th percentile latency (p95), concurrency and resource saturation. Saturation matters most here: under-used local infrastructure can cost more than the cloud, because its fixed cost is spread over few requests. There is no universal break-even point; it depends on your real volume, your hardware and current prices, and must be recalculated whenever one of them changes.
4. A decision tree enforced server-side
Routing a request comes down to a few questions asked in a set order: check that the transfer is allowed before comparing costs. Local processing is one of the approved destinations and is compared with the others on quality, latency and cost, with no built-in priority.
Text version of the diagram
- Is a deterministic rule or an approved cache sufficient? If yes, answer without new inference.
- If not, is cloud transfer allowed for this data, under the policy enforced server-side?
- If not allowed: is a suitable local or private option available? If yes, local or private inference; otherwise, wait or limited feature.
- If allowed: compare the approved options on quality, latency and cost, then choose local or private inference, or an approved cloud model.
The transfer decision belongs to a policy enforced server-side, based on data classification and the user's rights. A language model cannot grant itself that permission. If local processing is down, the feature degrades or waits; the outage never makes it acceptable to send prohibited content to the cloud.
Escalation to a more capable model also relies on validation: format checks, business rules, a score on an evaluation set, technical verification. The confidence a model reports in its own answer is not enough.
5. Confidentiality, sovereignty, security: three distinct questions
These three notions are often conflated, yet they raise different questions.
- Confidentiality: who can access prompts, outputs, documents, embeddings, caches and histories?
- Sovereignty: who controls hosting, administration, encryption keys and dependencies? Which jurisdictions, operators and subcontractors are involved?
- Security: how are access, exchanges, model artefacts and triggered actions protected?
Hosting in France or in Europe is not, on its own, proof of sovereignty. You also need to examine operators and administrators, key management, subcontractors, retention, backups, telemetry and ancillary services. Contractual terms must be checked provider by provider; no compliance is automatic.
Two shortcuts to avoid: "local = secure" and "cloud = insecure". A poorly configured internal server can expose more than a well-contracted, well-run cloud service, and a loosely governed cloud service can expose more than a well-run internal server.
6. Securing the whole chain
An AI feature passes through several links, each with its own controls.
- Application and backend: user authentication, authorisation per function and per resource, input validation, quotas, timeouts and size limits.
- Backend and inference: TLS encryption, a service identity for calling models, private networking or mutual authentication depending on risk level, an allow-list of destinations, secrets kept server-side and rotated according to policy.
- Data and RAG: access rights enforced before documents are returned, strict separation between customers, context minimisation, control of caches and their invalidation.
- Models: verification of provenance, licence, integrity and version; controlled downloads and updates.
- Outputs and tools: model outputs are treated as untrusted and validated. Business tools enforce access rights and least privilege themselves, and sensitive actions require human approval.
- Observability: log useful metadata (feature, model, version, tokens, latency, routing decision) without systematically recording the raw content of sensitive exchanges.
Embeddings, caches and histories can reveal sensitive information just as the source documents can; OWASP describes these forms of sensitive data exposure, including through a RAG system. Documents injected into the context can also carry malicious instructions: this is indirect prompt injection, for which OWASP considers limiting the model's privileges the most effective control.
On Windows PCs, Windows ML shows what these controls look like for on-device inference. The framework, built on ONNX Runtime, runs models directly on the device and accelerates inference on the NPU, GPU or CPU through execution providers that Windows installs and keeps up to date. Data stays on the device and processing works without a connection. The model can be included in the app package or downloaded separately; either way, its provenance, integrity and version need checking, and the app should be deployed through your device management tools like any business software. Execution providers optimised for NPUs require Windows 11 version 24H2 or later, which brings back the device compatibility question raised in the matrix.
7. A reference architecture
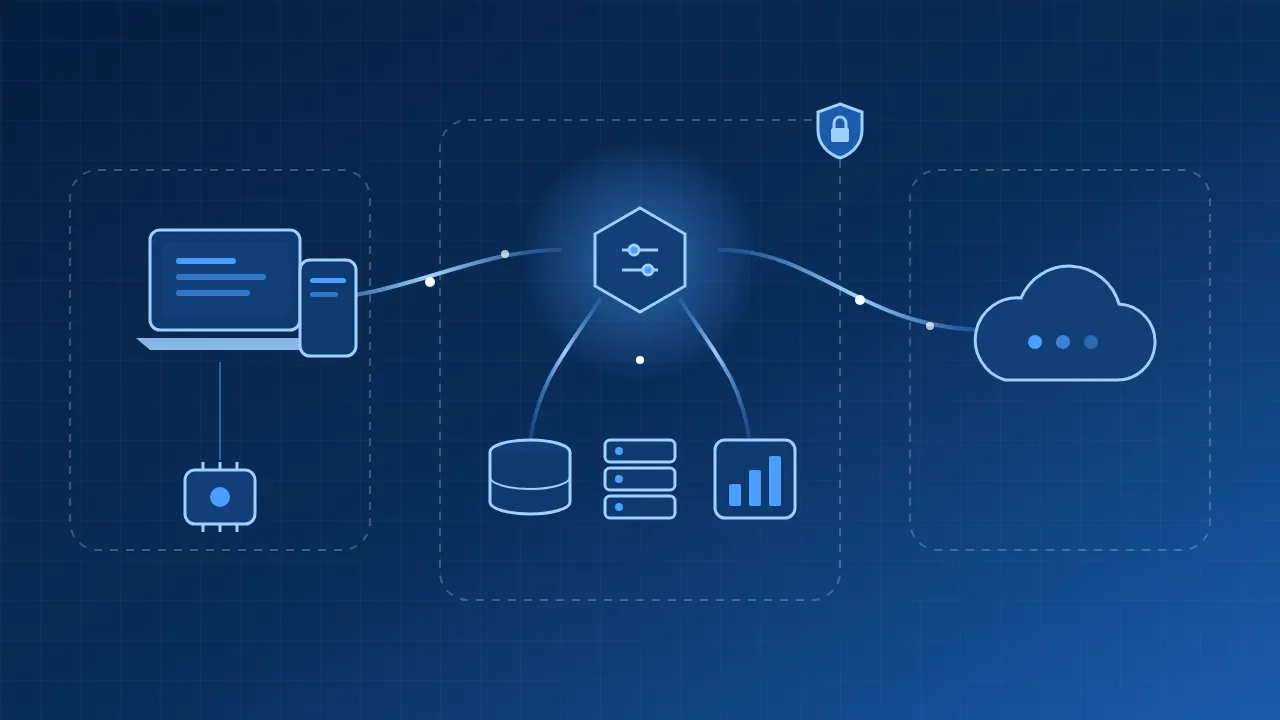
The architecture below combines two paths: on-device inference, and remote processing through a secure API. The frames mark trust boundaries; how secure each one is depends on the controls described above.
Text version of the diagram
- User device: the web or mobile app can call an embedded model if the device supports it. Offline operation requires the model, data and tools to be on the device.
- Controlled application environment: the app calls a secure API (identity, authorisation, quotas) over authenticated HTTPS, which passes requests to the orchestration layer (policies, budgets, routing, versions, fallback). Orchestration relies on data and retrieval with access rights enforced, private inference with approved models, and minimised quality and cost telemetry.
- Approved providers: orchestration can call a cloud inference API over TLS with a service identity, sending only the minimal approved context. Cloud keys are never embedded in the client.
The orchestration layer enforces data policies, budgets and quotas, selects the model and its version, sets timeouts and defines behaviour when a component is unavailable. The Microsoft Azure Architecture Center describes this role as a gateway placed in front of models: federated authentication, rate limiting, per-consumer usage tracking, caching and load balancing. The same guidance points out that a gateway sees raw requests and responses, expands the attack surface and therefore falls within the compliance scope itself.
In the diagram, the embedded model stays on the device; it is not a central service called remotely. Cloud API keys stay server-side and are never embedded in the client application.
8. Roll out gradually, measure, reassess
We recommend rolling out one use case at a time, in seven steps.
- Choose a use case with known volume and value, and a business owner.
- Build a representative evaluation set: common cases, edge cases, expected answers.
- Classify the data and define approved processing destinations.
- Measure the options (local, private and cloud) on that set: quality, latency, cost per validated task.
- Roll out gradually, by user group or share of traffic.
- Monitor quality and cost continuously, using the indicators described above.
- Reassess after every change of model, version, routing strategy or pricing.
Planning an AI use case for an application?
Let's discuss your use cases, your data constraints and how to measure quality and cost before scaling up.
Schedule a conversationSources
- EMAZIS, Hybrid AI in the Enterprise: Cloud vs. Local Is the Wrong Debate
- ONNX Runtime: Web (onnxruntime.ai)
- ONNX Runtime: Mobile, Android and iOS (onnxruntime.ai)
- Microsoft Azure Architecture Center: Access language models through a gateway
- Microsoft Learn: Optimise cost for AI workloads
- OWASP GenAI Security Project: Prompt injection
- OWASP GenAI Security Project: Sensitive data exposure
- Microsoft Learn: What is Windows ML?
Sources consulted on 10 November 2026. The request split example is hypothetical.